· Kirjoittaja: Denis Suciu
Claude Fable 5.2 is now in PocketPhantom
Anthropic's most capable model is now in PocketPhantom's model picker, on every paid plan. What Fable 5.2 is good for, what Anthropic measured and what it costs next to Fable 5.1.
Anthropic released Claude Fable 5.2 on 9 November 2026. It is the most capable model Anthropic offers to everyone, and it is now in PocketPhantom's model picker, next to Claude Opus, GPT and GLM. There is nothing to set up and no API key of your own to bring.
What it is good for
The hardest work: large code changes, research that takes many steps, maths and science, and long documents and data read closely. Anthropic says it explains itself more clearly than Fable 5.1, says so when it does not know something, and writes its answers up to 30% faster.
Like every Claude model in PocketPhantom, it reads text, images and PDFs, up to four files in a message. Web search is on unless you switch it off, and an answer names the pages it used.
What Anthropic measured
Anthropic reports these results from its own tests, against Fable 5.1, Claude Opus 5.5 and OpenAI's GPT-6 Astra:
- FrontierSWE v2, coding work in real software projects: 69.9%, ahead of GPT-6 Astra (65.5%), Opus 5.5 (62.3%) and Fable 5.1 (56.3%).
- Humanity's Last Exam with tools, expert questions across many fields: 74.2%, against 67.7% for Opus 5.5 and 57.2% for GPT-6 Astra.
- Terminal-Bench Science 0.1, science research tasks: 74.6%, up from 52.6% for Fable 5.1. GPT-6 Astra's 68.1% was the best score until now.
- Remote Labor Index, real paid freelance projects: 41.3%, more than twice Fable 5.1's 17.9%.
- Chartography, reading charts and figures: 73.4%, up from 44.8% for Fable 5.1.
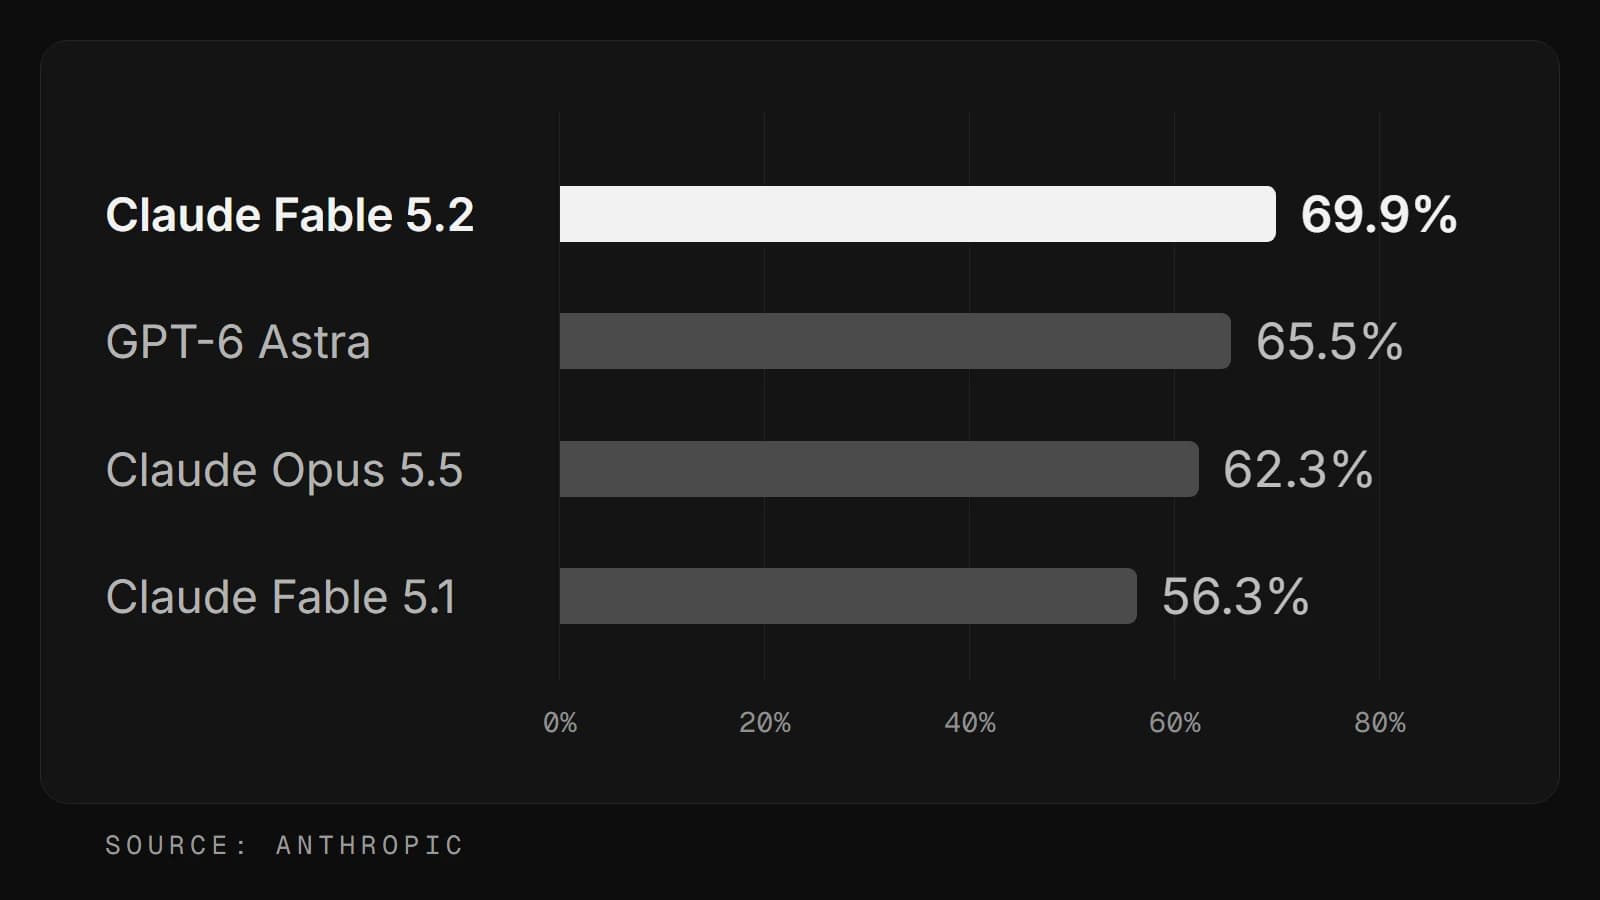
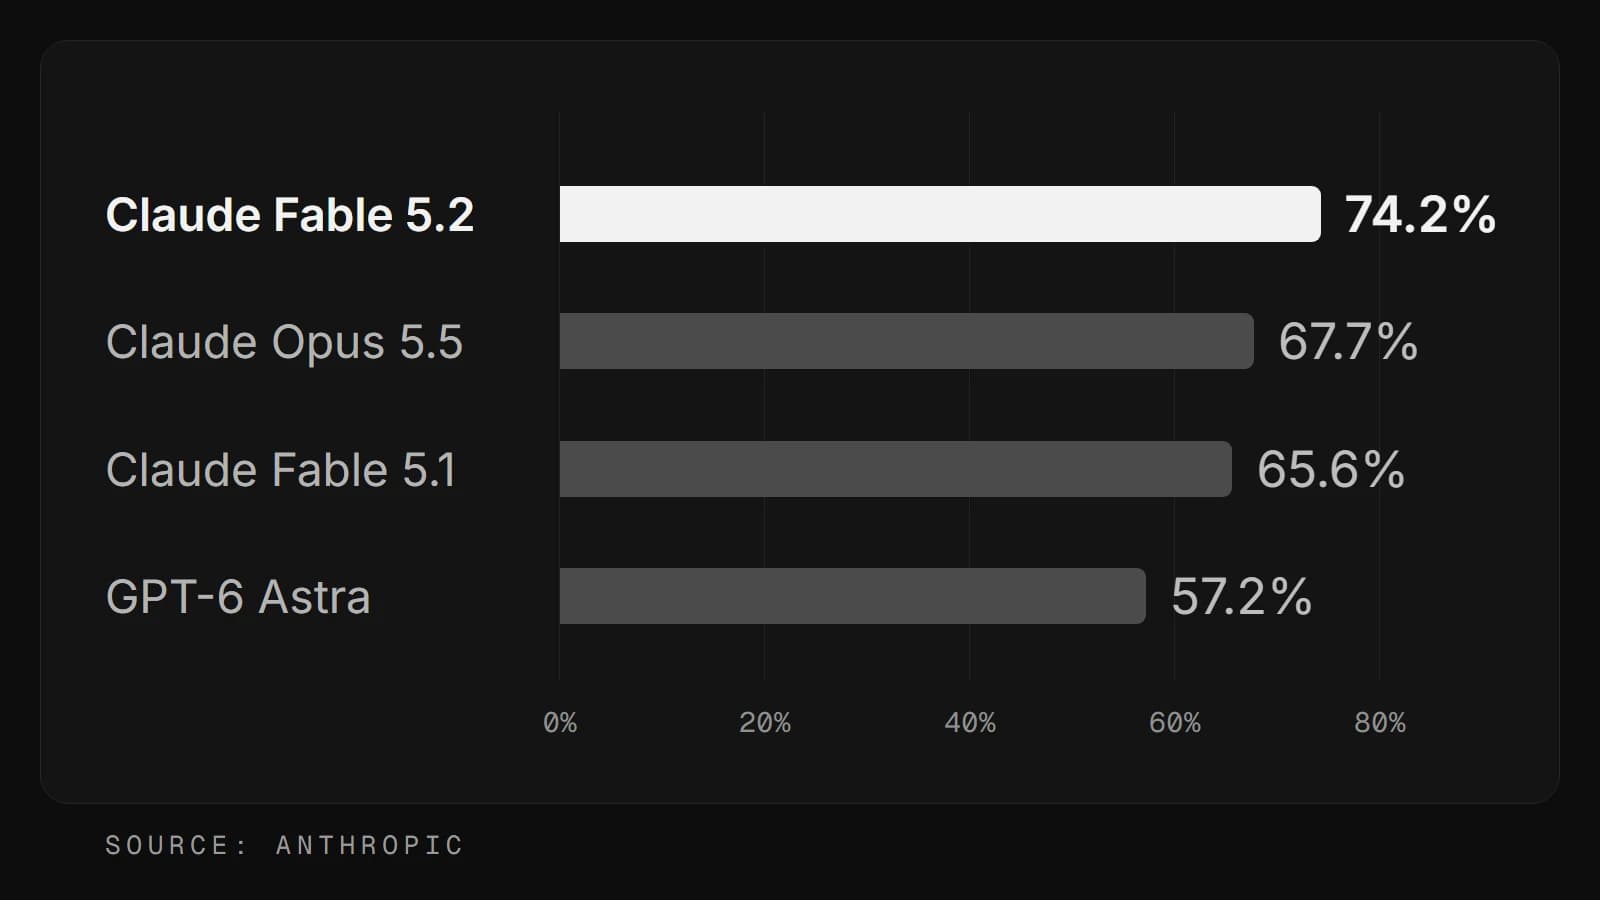
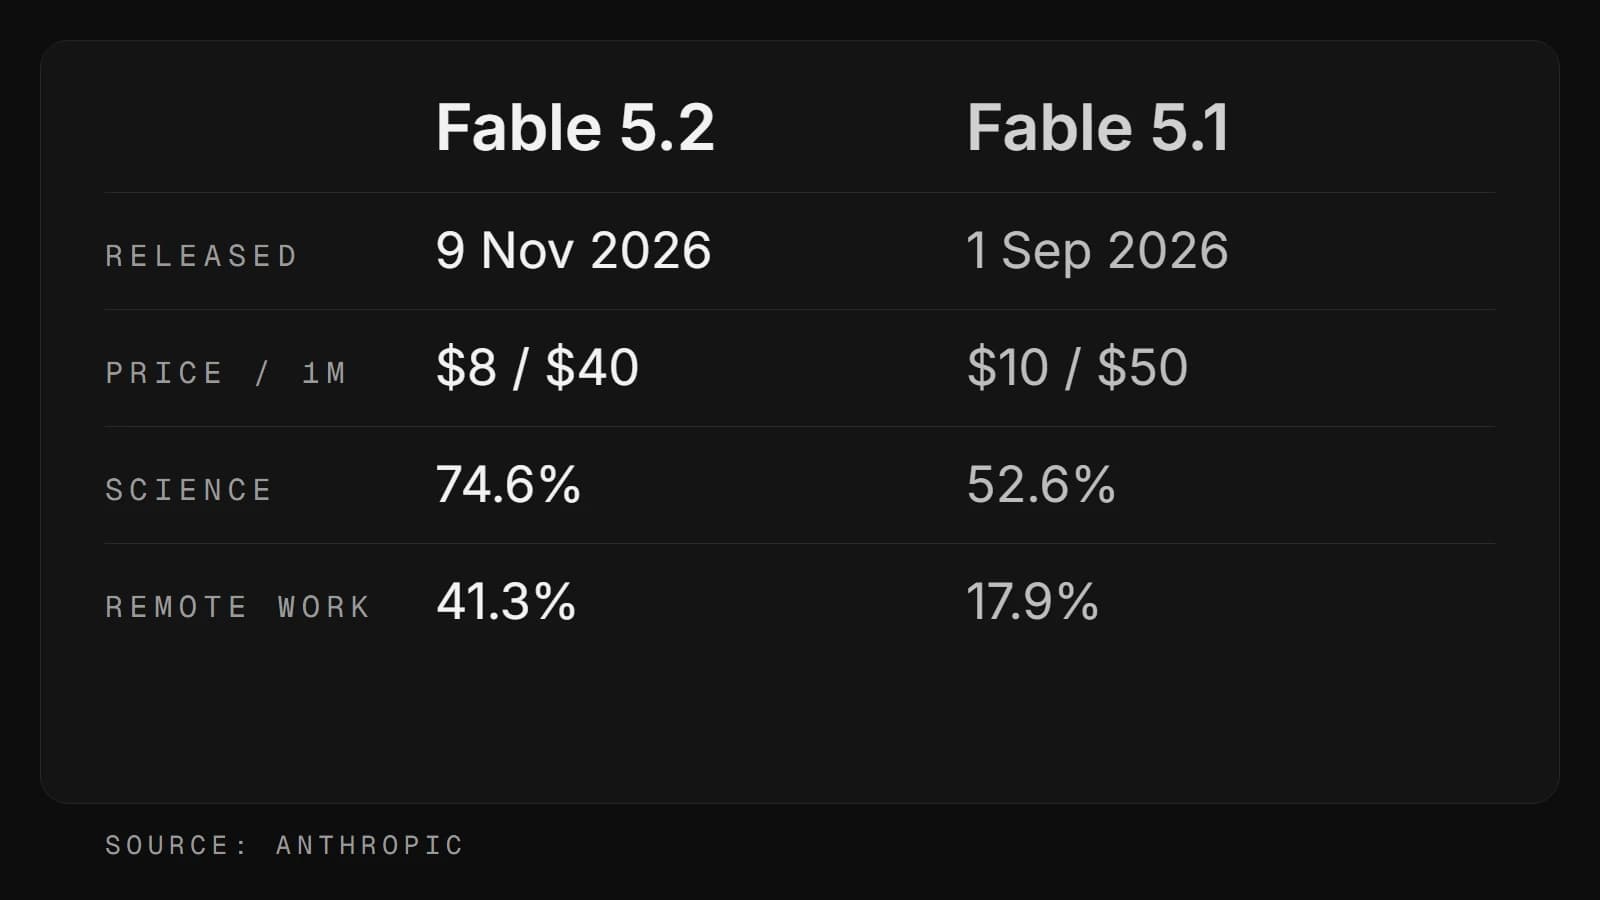
Anthropic ran most of these tests at the highest effort, which is Max in PocketPhantom, and some of them with the model working in a terminal, in a whole codebase or as a team of agents. PocketPhantom gives it no terminal or codebase to work in, so results in PocketPhantom can differ.
Sources: Anthropic's announcement and the Fable 5.2 model page.
Cheaper than Fable 5.1
Anthropic lowered the price: $8 per million input tokens and $40 per million output tokens, against $10 and $50 for Fable 5.1. Every token costs a fifth less, so the same question uses less of your monthly AI than it did on Fable 5.1.
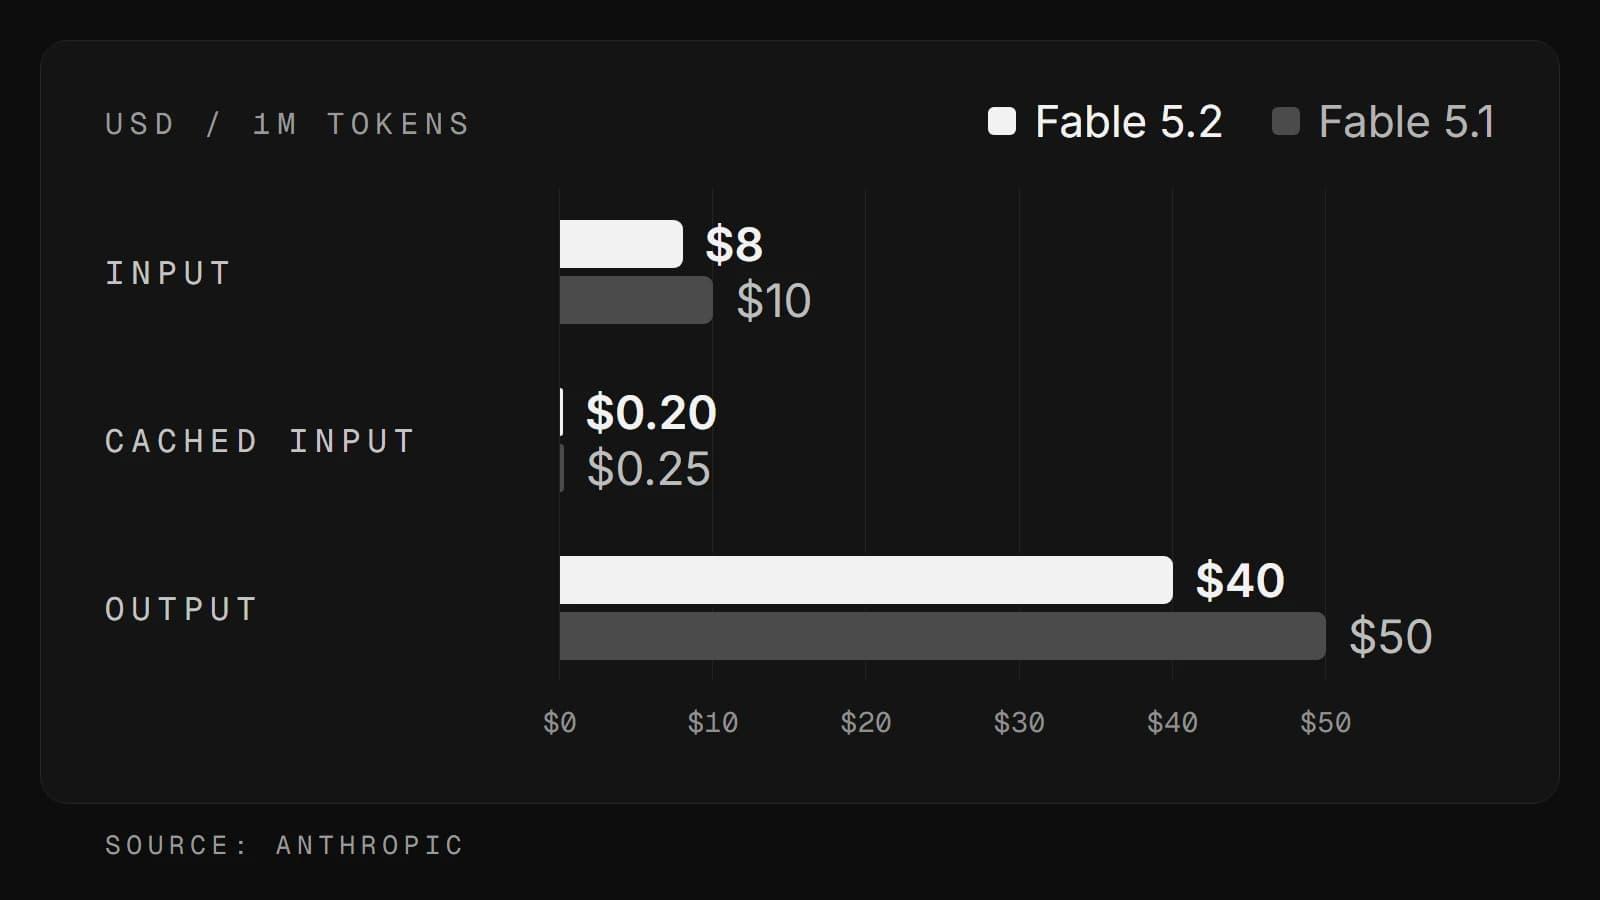
It is still the most expensive Claude model: Claude Opus 5.5 costs half as much. Anthropic itself suggests starting with Opus 5.5 for everyday work and moving up to Fable for the hardest jobs, and that holds in PocketPhantom too.
Which plans include it
Every paid plan includes it: Pro at $20 a month, Power at $60 and Max at $100 or $200. The plans differ in how much AI use they include each month. A bigger model or a higher effort uses more of it, and no plan is unlimited. Compare the plans.
The Free plan keeps to the lighter models, so it does not include Fable 5.2. On Free it shows a lock and the words “Comes with a paid plan”, and choosing it opens the plans. If you had picked Fable before, Claude Sonnet 5.5 answers in its place.
How to pick it
- Open the model pill in the chat bar: the button with the model's mark. On a phone it is the Model row in the plus menu.
- Type fable to narrow the list and choose Claude Fable 5.2 under Featured. The arrow keys and Enter work too.
- This browser remembers your choice.
On a paid plan, Auto now gives the hardest writing, code and document questions to Fable 5.2, where it gave them to Fable 5.1 before. Fable 5.1 stays in the picker as the previous Fable.
Effort
Effort is how long the model may think before it answers. The sliders button in the chat bar opens the effort rail; on a phone it is the Effort row in the plus menu. Pick Low, Medium, High or Max. Medium is the default and right for most things, and Anthropic says Fable 5.2 at Medium gets hard tasks done with fewer tokens than Fable 5.1. Longer thinking uses more of your monthly AI.
Models and effort in the docs describes every model and every level.